- Open source
- AI engineering
- RAG
- Agents
A document Q&A assistant that searches only when it needs to
- LangChain
- Pinecone
- bge reranker
- Groq · Llama 3.3 70B
- Node · Express
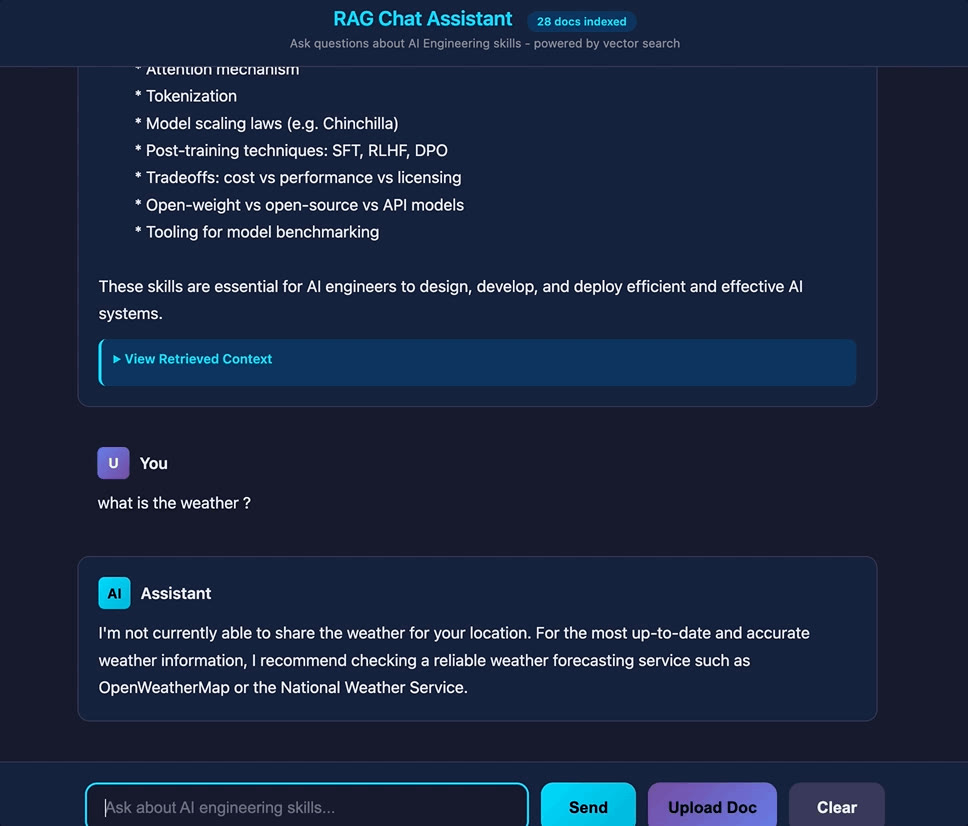
General-purpose chatbots answer from training data, not from your documents, and they make things up when they don’t know. Naive RAG fixes that but searches on every message — even “thanks” — and stuffs loosely related chunks into the prompt. I wanted retrieval only when needed, and only the passages that really match.
Two pipelines: ingest, then answer
What makes it more than a notebook demo
| Concern | Choice | Why |
|---|---|---|
| Precision | Retrieve 6, rerank with bge-reranker-v2-m3, keep 3 | Cheap recall first, then a cross-encoder picks what the LLM sees |
| When to retrieve | Retrieval is a tool the LLM calls | Small talk and follow-ups skip a needless search |
| Chunking | Recursive splitter, 500 chars / 100 overlap | Small enough to be precise; overlap keeps sentences intact |
| Simpler ops | Pinecone integrated embeddings, serverless index | No separate embedding service to run or keep in sync |
| Latency | Groq inference | ~200 ms search + rerank, 1–3 s answer (measured locally) |
| Transparency | Response returns toolsUsed and context |
The UI shows exactly which passages backed the answer |
What I’d build next
- Streaming responses
- Hybrid search (keyword + vectors)
- Query logs, tracing and a golden-set eval
- Authentication, then a public deployment